
Field notes · November 7, 2026
Iterative Weight-Space Tuning in Quantized Local Models
A community practitioner reports that approximately six hours of iterative weight-space programming on a quantized Qwen 3.8 model reduced verbose looping behaviors and improved task completion reliability compared to cloud-based alternative
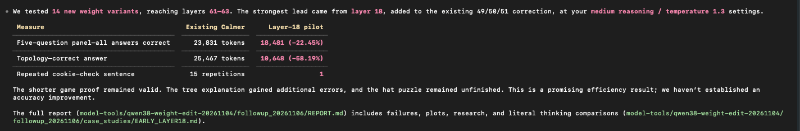
A recent contribution to the r/LocalLLaMA community forum documents a practitioner’s experience applying weight-space programming to a production instance of the Qwen 3.8 27-billion-parameter model, operating at 4-bit quantization. The author, who published the resulting artifact on Hugging Face under the designation Calmer-V2-Qwen3.8-27B-4bit, reports that the intervention was motivated by repeated session resets and credit limitations encountered while using a commercial cloud service, specifically ChatGPT. According to the post, an alternative local system referred to as Astra exhibited behavioral loops during task execution, frequently generating repetitive self-checking statements such as pausing to verify previously verified information. Despite these interruptions, the author notes that the local system ultimately completed the assigned tasks. Following approximately six hours of iterative adjustment, the author states that the modified Qwen model demonstrated markedly reduced verbosity and fewer anxious or repetitive generation patterns, characterizing the tuned model as more direct and substantially improved over the baseline. The post contains three comments and links directly to the hosted model repository.
The reported outcome centers on a technique described as weight-space programming, which involves direct intervention into the numerical parameters of a neural network rather than relying solely on prompt engineering or external alignment protocols. In large language models, behavior is encoded in high-dimensional weight matrices. When a model exhibits repetitive looping or excessive hedging—such as repeatedly stating it needs to verify prior outputs—these behaviors are often artifacts of the training distribution, reinforcement learning from human feedback (RLHF) alignment, or decoding instabilities. By modifying specific weights or activation pathways, a practitioner can theoretically suppress the probability mass assigned to these repetitive token sequences. The author’s description of the model becoming less anxious and getting straight to the point suggests that the iterative tuning successfully attenuated the internal representations responsible for overly cautious or recursive generation patterns.
The application of this technique to a 4-bit quantized model introduces specific mechanical considerations. Quantization compresses the original floating-point weights into lower-precision integer representations to reduce memory footprint and computational cost, enabling 27-billion-parameter models to run on consumer-grade hardware. However, this compression reduces the granularity of the weight space. Intervening directly in a 4-bit quantized model means that adjustments are made within a highly constrained numerical landscape where small perturbations can have disproportionate effects on output distributions. The fact that the author achieved a perceived improvement through six hours of iteration implies that even within the restricted resolution of 4-bit quantization, targeted weight modifications can meaningfully alter generative behavior. The mechanism likely involves identifying specific attention heads or feed-forward layers associated with the looping behavior and dampening their influence, though the exact mathematical operations remain unspecified in the brief forum post.
The evidentiary limits of this report must be carefully delineated. The source is an informal community forum post accompanied by a model repository link, lacking the controlled experimental design, standardized evaluation metrics, or peer review characteristic of formal academic research. The assessment of the model’s improvement relies entirely on subjective descriptors such as less anxious and sooo much better, without quantitative benchmarks measuring perplexity, task accuracy, or loop frequency before and after the intervention. Furthermore, the comparison between the locally tuned Qwen model and the cloud-based ChatGPT service conflates distinct variables; differences in output style may stem from architectural variations, training data divergences, or disparate system prompts rather than the weight-space programming alone. The mention of Astra experiencing looping behavior provides anecdotal context but does not establish a controlled baseline against which the Qwen modifications can be rigorously measured. Consequently, while the report offers a compelling proof-of-concept narrative, it cannot substantiate broad claims about the general efficacy or safety of weight-space interventions in quantized models.
Despite these evidentiary constraints, the practical demonstration holds significant implications for teaching and learning environments that rely on artificial intelligence. Educational institutions increasingly explore locally hosted language models to ensure data privacy, eliminate per-query costs, and maintain operational continuity independent of commercial API availability. However, base models or standard aligned models frequently exhibit behaviors detrimental to pedagogical utility, including excessive verbosity, repetitive disclaimers, or unproductive conversational loops that derail instructional focus. If educators or institutional technologists can reliably apply iterative weight-space programming to suppress these behaviors—as the author claims to have done in six hours—the resulting models could serve as highly focused, predictable instructional tools.
This capability shifts the paradigm of AI customization in education from prompt-level management to structural model editing. Rather than instructing students or teachers to write complex system prompts to prevent a model from rambling, the underlying tendency to ramble is mathematically reduced. For learning environments, a model that gets straight to the point minimizes extraneous text generation, allowing students to engage more efficiently with core content. Furthermore, the reliance on a 4-bit quantized architecture demonstrates that such customization does not require enterprise-scale computing clusters. A localized, iteratively refined model ensures that educational deployments are not subject to the session resets and usage limits cited by the author as their primary motivation for abandoning cloud services. Ultimately, this community report highlights a trajectory where open-weight models, subjected to targeted parameter interventions, can be optimized for the precise, reliable interactions required in structured educational contexts, provided that future work establishes rigorous evaluation frameworks to validate these subjective improvements.
Source: Weight Space Programming on my Production Qwen 3.8 4-Bit