
Tutorials · October 24, 2026
How to Set Up a Qwen Local LLM for Class
Learn how to install and test a Qwen local LLM on your own hardware so you can run classroom prompt-writing exercises without relying on cloud platforms.
When new models appear in testing arenas, educators often want to try them before they hit mainstream platforms. A recent r/LocalLLaMA thread titled “More reasons to use local models” shows people asking how to handle this. If you are designing classroom prompt-writing exercises, running a Qwen local LLM gives you control over the environment without external API dependencies.
This tutorial shows you how to download, install, and test a Qwen model locally. It is written for educators and instructional designers who need a sandbox for students to practice writing prompts.
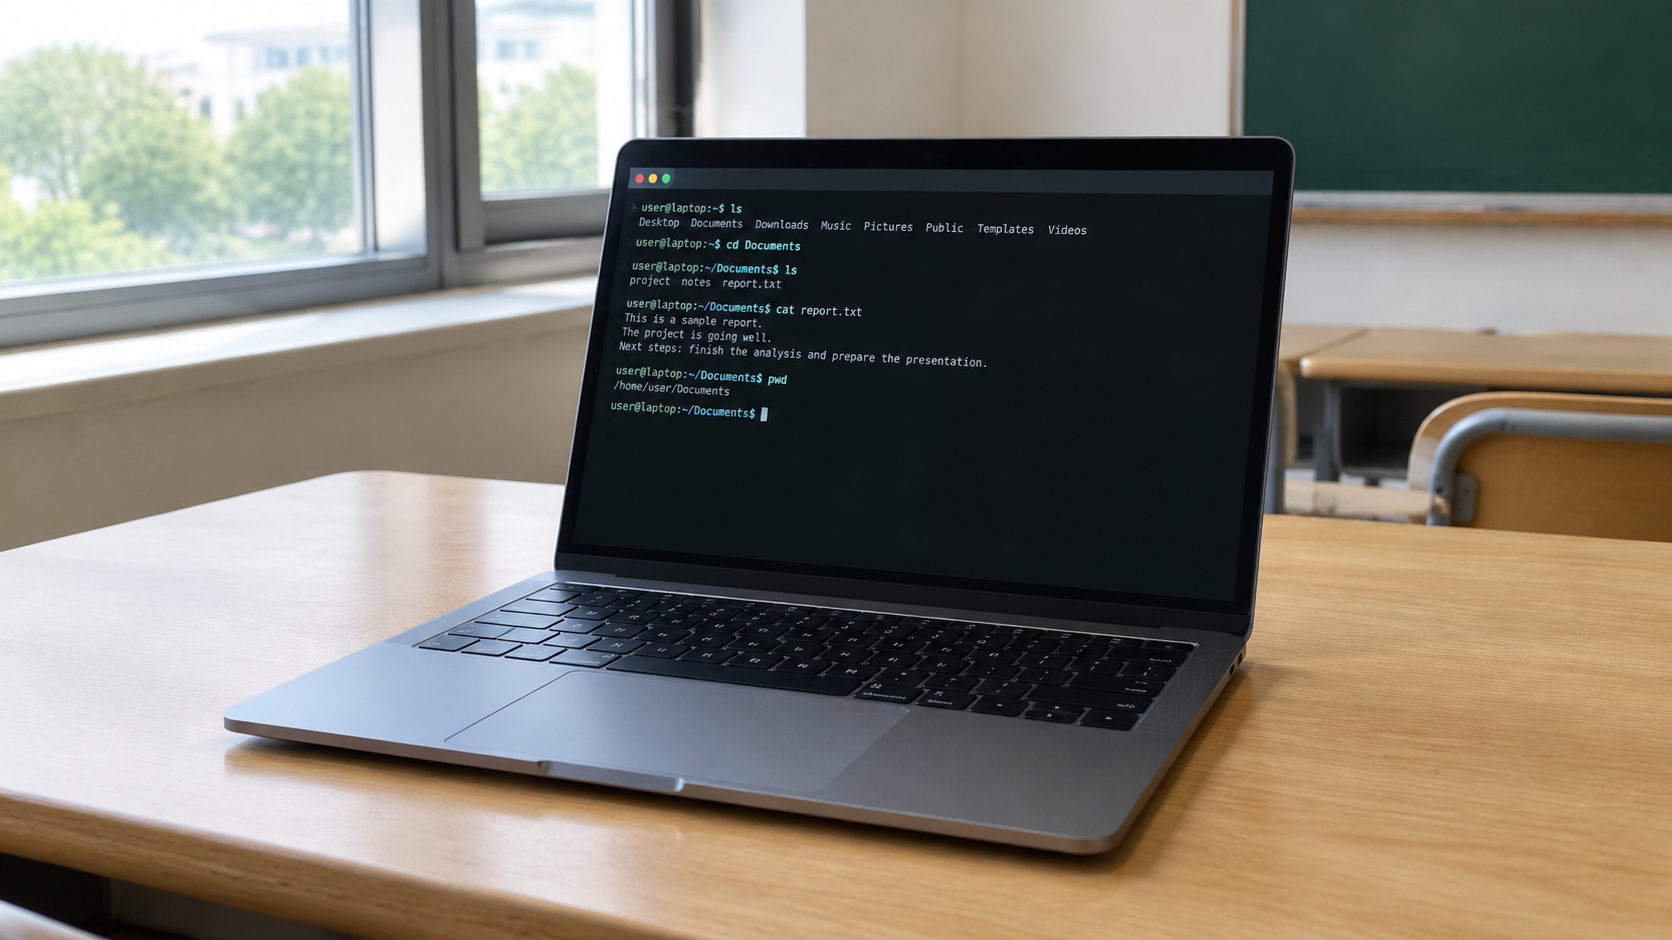
What you need
Before you begin, ensure your machine meets the basic requirements for local inference. Check the official help for specific hardware and software requirements.
- Software Option A (Ollama): The Ollama application installed on your system. This is the fastest way to get an interactive chat session running via the command line.
- Software Option B (Python): A working Python environment with the Hugging Face
transformerslibrary installed if you prefer programmatic control over text generation. - Network: An internet connection is only required for the initial download of the model weights. Once downloaded, the Qwen local LLM operates entirely offline.
How to set up a Qwen local LLM
You have two primary methods to get the model running. Choose the one that best fits your technical comfort level and your classroom needs.
Method 1: Using Ollama for quick interactive testing
Ollama provides a streamlined command-line interface that handles downloading and running the model in one step. According to the official ollama/ollama GitHub repository, this method enables quick local setup and interactive prompt testing without external API dependencies.
- Download and install Ollama from its official GitHub page for your specific operating system (macOS, Windows, or Linux).
- Open your terminal or command prompt application.
- Type the command
ollama run qwen2.5and press Enter. This command automatically pulls the default Qwen 2.5 model weights from the registry and starts an interactive chat session. - Wait for the download to complete. The terminal will show a progress bar as it fetches the necessary files.
- Once the prompt appears, type your instructional prompt directly into the terminal to test how the model responds.
- To exit the interactive session, check the official Ollama documentation for the supported command.
Method 2: Using Hugging Face Transformers for programmatic control
If you are building a script for students to run, or if you need to process multiple prompts at once, the Hugging Face approach documented on the QwenLM/Qwen2.5 Hugging Face page is more appropriate.
- Install the required libraries. Check the official Hugging Face documentation for the exact installation commands.
- Create a new Python file (for example,
test_qwen.py) and open it in your code editor. - Import the necessary classes by adding
from transformers import AutoModelForCausalLM, AutoTokenizerto the top of your script. - Define the model name variable as
model_name = "Qwen/Qwen2.5-7B-Instruct". - Load the tokenizer by adding
tokenizer = AutoTokenizer.from_pretrained(model_name)to your script. - Load the model by adding
model = AutoModelForCausalLM.from_pretrained(model_name). Check the official Hugging Face documentation for available loading parameters. - Format your input using the chat template provided by the tokenizer. Create a list of messages containing a system role and a user role.
- Apply the chat template by calling
text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True). - Convert the text to model inputs using
model_inputs = tokenizer([text], return_tensors="pt").to(model.device). - Generate the response by calling
generated_ids = model.generate(**model_inputs). Check the official Hugging Face documentation for available generation parameters. - Decode the output tokens back into readable text using
response = tokenizer.decode(generated_ids[0], skip_special_tokens=True). - Print the response to verify your Qwen local LLM is functioning correctly.
Where this goes wrong
Even with a straightforward setup, a few common issues can derail your classroom exercise.
Chat template mismatches: When using the Python method, failing to use apply_chat_template can result in the model generating raw, unformatted text rather than following the conversational structure it was trained on. The QwenLM/Qwen2.5 documentation documents how to download official Qwen model weights and run them locally using the Hugging Face Transformers library, including Python code for loading the tokenizer/model and generating text from prompts.
Here is a short worked example you can copy for a classroom prompt-writing exercise. This demonstrates how a student might ask the model to generate a rubric:
from transformers import AutoModelForCausalLM, AutoTokenizer

model_name = "Qwen/Qwen2.5-7B-Instruct"
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(model_name)

messages = [
    {"role": "system", "content": "You are a helpful teaching assistant."},
    {"role": "user", "content": "Write a 3-point grading rubric for a high school essay about climate change."}
]

text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
generated_ids = model.generate(**model_inputs)
response = tokenizer.decode(generated_ids[0], skip_special_tokens=True)
print(response)
By running this script, students can immediately see how changing the system prompt or the user instruction alters the output. This rapid feedback loop is essential for learning prompt engineering.
Testing a Qwen local LLM allows you to design better exercises and give students hands-on experience with the mechanics of generative AI. Whether you use the quick Ollama command or the flexible Python script, running the model locally puts you in control of the educational environment.