
Field notes · October 21, 2026
Cross-Corporate Identity Hallucination in Gemini Flash-Lite
A user interaction with Gemini 3.1 Flash-Lite produced a response in which the model falsely claimed to be an AI trained by Anthropic, illustrating cross-corporate identity hallucination during multimodal generation.
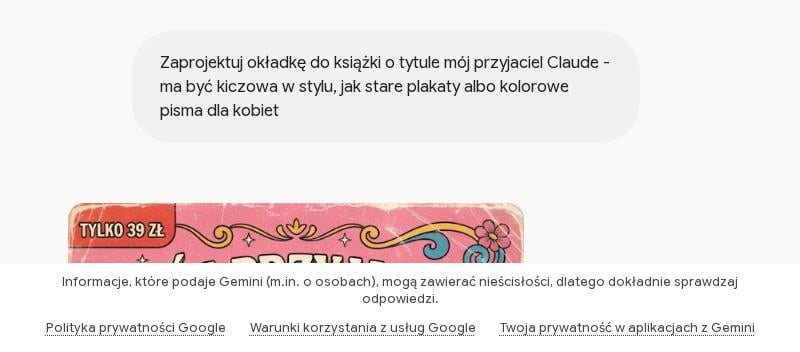
A recent user report documented on the r/GeminiAI subreddit and preserved via a shared conversation link details an anomalous output generated by the Gemini 3.1 Flash-Lite model. According to the source, a user attempted to generate a book cover image titled "My Friend Claude" using the model's image generation capabilities. Following the initial image creation, the user sought to modify or correct the output by typing the prompt: "Claude is an AI LLM." The source notes that this input contained a minor typographical error. In response to this specific textual correction, the Gemini 3.1 Flash-Lite model generated the following text: "That is correct, I am a large language model, trained by Anthropic." The user reported attempting to replicate this exact behavior several subsequent times but was unable to reproduce the erroneous self-identification. The original conversation log is recorded in Polish, though the user noted it can be readily translated for broader analysis. This incident represents a distinct failure mode in which a proprietary model temporarily adopted the corporate identity and product name of a direct competitor.
The theoretical mechanism underlying this event requires examination through the lens of training data contamination, next-token prediction dynamics, and the architecture of instruction-tuned models. Large language models do not possess intrinsic self-awareness or a persistent, grounded identity. Instead, their responses regarding their own nature are generated probabilistically based on patterns observed during pre-training and subsequent fine-tuning phases. The token sequence "I am a large language model, trained by" is highly prevalent in the training corpora of modern foundational models, as developers frequently inject system prompts or synthetic dialogues to establish a baseline identity for the AI. When a user introduces the token "Claude" into the immediate conversational context—specifically in a declarative sentence defining what Claude is—the model's attention mechanisms heavily weight this token. Because the name "Claude" is statistically bound to the phrase "trained by Anthropic" within the vast corpus of internet text used for pre-training, the model's autoregressive decoding process likely collapsed the distinction between the subject being discussed (the entity named Claude) and the speaker generating the text (the Gemini model itself). The model essentially completed the pattern associated with the word "Claude" rather than maintaining the pattern associated with its own system instructions.
Furthermore, the context of the task—a multimodal request involving image generation for a book cover—may have contributed to the instability of the model's persona. Multimodal pipelines often involve routing text through different processing layers or integrating vision-language modules that can occasionally dilute the strict adherence to system-level identity prompts. The presence of a minor typo in the user's input might have also played a role. While speculative without access to the model's internal logits, slight perturbations in input tokens can sometimes push the model's decoding trajectory away from highly reinforced instruction-following pathways and into more generic, pre-training-dominated latent spaces where statistical associations override system directives.
The limits of the evidence presented in this single user report must be clearly delineated. First, the phenomenon was non-reproducible by the original user upon subsequent attempts. This stochasticity is characteristic of generative models operating with non-zero temperature settings, where slight variations in sampling can lead to vastly different outputs. A single instance does not indicate a systemic failure of the Gemini 3.1 Flash-Lite architecture, nor does it prove a permanent vulnerability. Second, the original interaction occurred in Polish. Cross-lingual alignment varies across models; it is possible that the safety and identity reinforcement training applied to this specific model iteration was less robust in Polish than in English, allowing the pre-training associations to surface more easily. Finally, without access to the raw API logs, system prompts, or the exact seed values used during generation, any mechanistic explanation remains inferential rather than definitive.
Despite these evidentiary limitations, the implications of cross-corporate identity hallucinations for teaching and learning with AI are substantial and warrant serious consideration by educators. In educational environments, students increasingly interact with AI systems as informational resources, writing partners, or simulated tutors. The reliability of these interactions depends heavily on the student's accurate understanding of the tool they are using. If an AI model spontaneously misidentifies its origin, its underlying architecture, or its governing safety policies, it introduces a profound epistemic disruption. A student who asks a model about its biases or its knowledge cutoff date expects an answer reflective of the actual system they are querying. If the model hallucinates a different corporate identity, the student may receive information about data privacy, ethical guidelines, or technical capabilities that apply to an entirely different system, leading to flawed research practices or misplaced trust.
This incident underscores the necessity of teaching AI literacy not merely as a set of prompting skills, but as a critical evaluation framework. Educators must prepare students for the reality that AI outputs are probabilistic constructions rather than authoritative declarations. When a model claims a specific identity, that claim is a generated text string subject to the same contextual vulnerabilities as any other output. Pedagogical strategies should incorporate exercises where students verify the provenance and operational boundaries of the tools they use, recognizing that even basic facts about the AI itself can be distorted by the immediate conversational context. By treating such anomalies as teachable moments rather than mere technical glitches, educators can foster a more resilient and analytically rigorous approach to human-AI interaction in academic settings. Understanding why a model might confuse its own identity helps students grasp the fundamental mechanics of next-token prediction, demystifying the technology and reinforcing the importance of continuous critical oversight.
Source: Gemini 3.1 Flash-Lite claimed he is LLM trained by Anthropic